Contents
- 23 Oct 2026
ETL Process Optimization for Big Data: Fix the Slowest Stage
ETL process optimization is the practice of making a data pipeline faster, cheaper, or more reliable by changing what work it does, where it runs, and how it is scheduled. The dependable method is to measure per-stage runtime first, then fix the slowest of four stages: extraction (incremental loads and early filtering), transformation (set-based logic, parallelism, and ELT pushdown), loading (bulk, partitioned, repeatable writes), and storage (columnar formats and data layout). In favorable cases, this cuts big data pipeline runtimes by an order of magnitude, but speed, cost, and reliability pull in different directions, so set the target before you tune.
As data volumes grow, the difference between a pipeline that finishes in minutes and one that runs for days is rarely more compute. It is usually one slow stage that nobody measured. This article, which applies equally to data pipeline optimization and big data ETL, shows how to find that stage and fix it, with specific techniques for Spark and cloud warehouses, a symptom-to-fix table, and a retail example that went from 24 hours to under two. For related solution work, see our ETL data transformation solutions.
Quick Summary

- Share Post:
-

-

Key Takeaways
- Measure before you tune. Per-stage runtime, rows and bytes moved, spill, and cost per run show where the time actually goes.
- Fix the slowest stage, not all four. Adding compute to the wrong stage raises cost without raising speed.
- Move less data first. Incremental extraction and early filtering usually beat any downstream tuning.
- Replace row-by-row work. Set-based logic and bulk loads are the most common wins in transformation and loading.
- Layout is a performance feature. Columnar formats, partitioning or clustering, and avoiding tiny files make every later read cheaper.
- Runtime, cost, and reliability conflict. Pick the target and measure it, or you may speed up a job and raise its bill.
What Is ETL Process Optimization?
ETL process optimization improves the speed, cost, and reliability of extraction, transformation, and loading by cutting unnecessary data movement, parallelizing work, and pushing transformations closer to the data. Each step- extract, clean, transform, and load- can become the bottleneck at scale, so optimization means finding the slowest stage and fixing it, not just adding compute. The same approach applies more broadly to data pipeline optimization, whether the pipeline is ETL or ELT.
Big data changes the math because workloads outgrow a single machine's memory and require distributed frameworks like Apache Spark. Structured records, semi-structured logs, unstructured content, and IoT streams each need different transformation logic, and an inefficient pipeline translates directly into a higher cloud compute bill. Our guide to data transformation best practices in ETL pipelines covers the logic side in more depth.
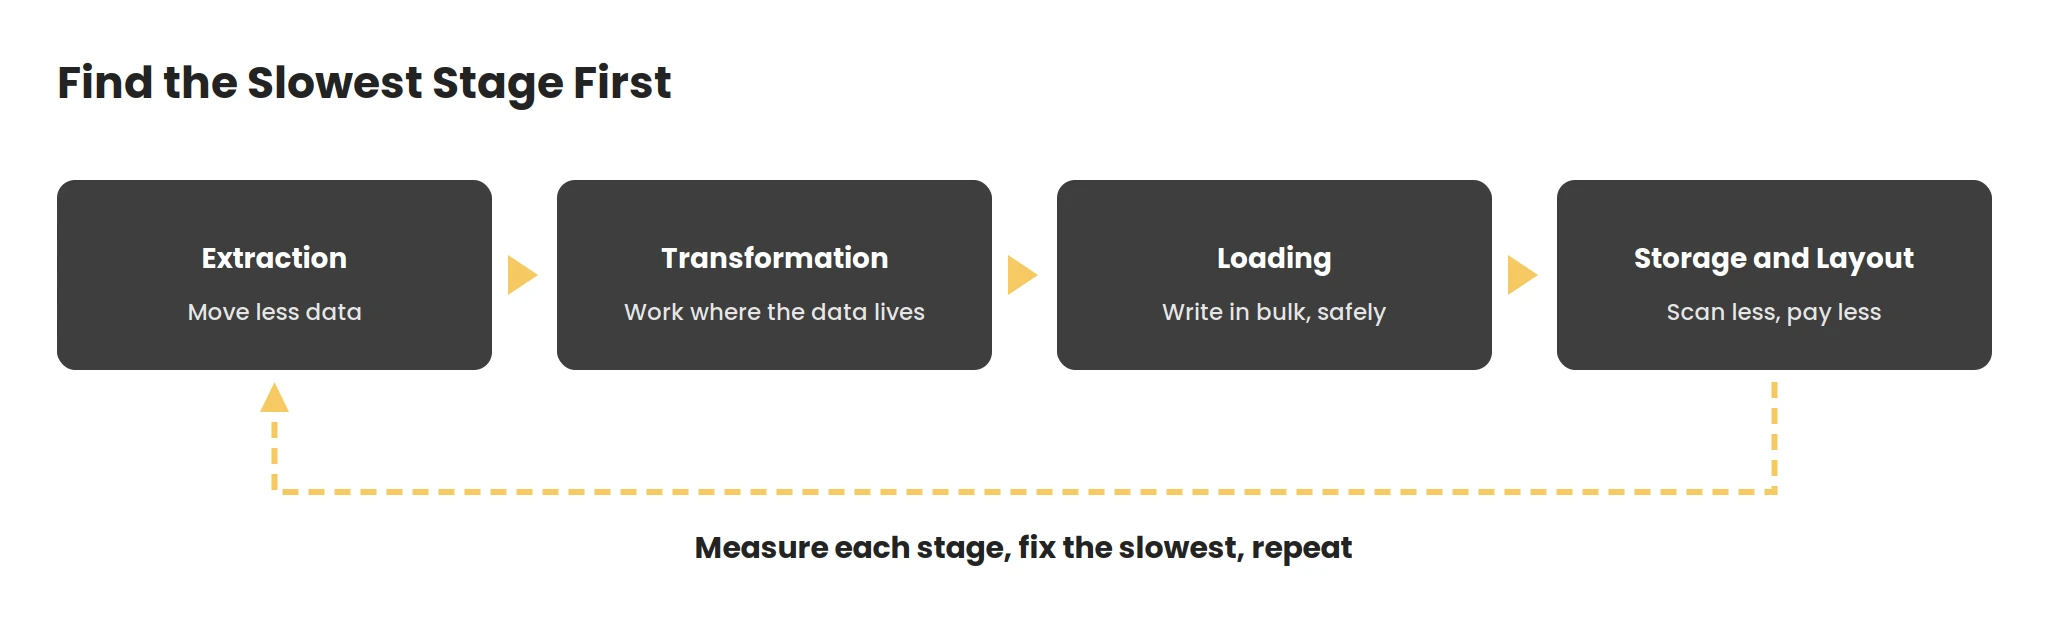
The four stages of an ETL pipeline and the loop for optimizing them.
Measure First: Build a Baseline
You cannot optimize what you do not measure. Before changing anything, capture a baseline for each stage:
| Metric | Why It Matters | Where to Look |
|---|---|---|
| Runtime per stage | Shows which of the four stages is the bottleneck | Orchestrator logs, job history |
| Rows and bytes in and out | Reveals unnecessary data movement and failed filters | Pipeline metrics, source and target counts |
| Shuffle volume and spill to disk | Signals oversized partitions and expensive joins | Spark UI stage details |
| Task time spread (slowest vs median) | A large gap points to data skew | Spark UI task metrics |
| Cost per run | Keeps a faster job from becoming a pricier one | Cloud billing and cluster metrics |
| Failure and retry rate | Reliability problems often hide as runtime problems | Scheduler and job logs |
For tool-specific monitoring, see how session-level logging works in Informatica tracing levels and how to tune workflows for efficiency in our Informatica PowerCenter workflow efficiency strategies.
Extraction: Move Less Data
| Technique | What It Does | Watch Out For |
|---|---|---|
| Incremental loading and CDC | Extracts only new or changed records instead of the full dataset every run | Needs reliable change keys, and deletes must be handled explicitly |
| Early filtering and column selection | Pushes WHERE clauses and column lists to the source system | Avoid SELECT * on wide tables |
| Parallel reads | Splits a large table by key range so several readers pull at once (for example, partitioned JDBC reads in Spark) | Do not overload a production source system |
| Chunking | Processes large datasets in batches instead of loading everything into memory | Choose batch sizes against memory, not guesswork |
Transformation: Do the Work Where the Data Lives
| Technique | What It Does | Watch Out For |
|---|---|---|
| Favor ELT on cloud warehouses | Runs transformation inside Snowflake, BigQuery, Redshift, or a lakehouse, using scalable columnar compute instead of a separate ETL server | Sensitive data may need masking before it lands |
| Set-based logic over row-by-row | Uses built-in functions instead of Python UDFs, cursors, or loops, as in our PL/SQL conversion article | Literal translation of procedural code runs slowly on Spark |
| DataFrames and SQL over RDDs | Let Spark's Catalyst optimizer plan the work | RDD code bypasses that optimizer |
| Broadcast joins for small tables | Sends a small table to every node to avoid a shuffle | Spark broadcasts automatically only below a size threshold (10 MB by default), so check your platform's setting |
| Right-sized partitions and skew handling | Balances work across nodes; Spark's adaptive query execution, on by default since Spark 3.2, can coalesce partitions and split skewed joins | Defaults vary by platform, so confirm yours |
| Selective caching | Keeps reused data in memory | Caching everything wastes memory and can slow a job |
| Efficient data types | Converts loose strings into numeric, date, or categorical types early | Mismatched types cause silent changes, as in our Databricks migration services overview |
Parallelism, cloud-native services, and serverless execution all apply here, as covered in our articles on serverless ETL for large-scale transformation and cloud-based ETL for structured and unstructured data.
Loading: Write in Bulk, Safely
| Technique | What It Does | Watch Out For |
|---|---|---|
| Bulk loads and MERGE | Uses bulk utilities or upsert statements instead of row-by-row inserts, which are the most common cause of slow loads | Test MERGE conditions on real data |
| Repeatable (idempotent) loads | Lets a failed job rerun without duplicating rows | Needs stable keys or load markers |
| Partitioning by date | Limits the data scanned by downstream queries | Over-partitioning creates many tiny files |
| Index handling during load | For relational targets, drop or disable indexes before a bulk load and rebuild afterward | Applies to databases like SQL Server or Oracle, not to warehouses such as Snowflake that do not use traditional indexes |
| File sizing | Writes files large enough to read efficiently, and compacts small files | Too-large files reduce read parallelism |
Slow Python pipelines often trace to the load step, as our guide to ETL pipeline automation with Python explains, and orchestration choices are covered in ETL workflow automation with Apache Airflow.
Storage and Layout: Store Data for the Query
- Use columnar formats for analytics. Parquet and ORC are columnar and dramatically improve read performance. Avro is row-based, so it suits streaming and schema evolution better than analytical scans, a point our article on handling schema evolution in ETL expands on.
- Enable data skipping. Liquid clustering on Databricks, clustering keys on Snowflake, and partitioning and clustering on BigQuery let queries skip irrelevant blocks instead of scanning whole tables.
- Compact small files. Many tiny files slow every read, so schedule compaction (for example, OPTIMIZE on Delta tables).
- Monitor and review. Run time and read execution plans regularly, then re-measure after every change.
ETL vs ELT: Where to Transform
In ETL, transformation happens before loading, on a separate processing layer. In ELT, you load data first and transform it inside the warehouse using its scalable, columnar compute. Cloud platforms make ELT faster and cheaper in many cases, but ETL remains the right choice when data must be masked or filtered before it lands. We cover the trade-offs in our comparison of traditional vs modern ETL, and the broader framework choice in our ETL framework comparison for cloud migration.
Common Bottlenecks and Fixes
| Symptom | Likely Cause | Fix |
|---|---|---|
| Large transfers dominate runtime | Full reloads and unfiltered extracts | Incremental loading, early filtering, column selection |
| One task runs far longer than the rest | Data skew on a join or group key | Adaptive query execution, salting hot keys, broadcast the small side |
| Job slows as data grows | Poor partitioning or a full scan every run | Partition and cluster on the filter keys, review partition counts |
| Memory spills to disk | Partitions too large or too much cached data | Repartition, reduce cached data, right-size the cluster |
| Transforms are fast, but the job is slow | Row-by-row inserts at load time | Bulk loads and MERGE |
| Transformation stage is slow | Excessive or row-by-row logic | Push down to the warehouse (ELT), simplify, use set-based functions |
| Queries are slow after loading | Wrong format or poor layout | Columnar formats, clustering, compaction, query tuning |
Speed, Cost, or Reliability: Pick the Target
Optimization goals pull in different directions. Doing less work, such as smaller scans and smaller shuffles, usually lowers both cost and runtime. Adding parallelism lowers runtime but can raise cost, and extra validation and retries improve reliability at the cost of speed. Decide which of the three you are optimizing, write down the target number, and track cost per run beside runtime so a faster job does not quietly become a more expensive one. For platform choices that affect cost, see high-performance ETL tools for real-time data processing and cloud-based ETL advantages.
Example: 24 Hours Down to Under Two
A retail company with 100+ stores took over 24 hours to process daily sales data across multiple systems, too slow for same-day decisions. By applying distributed partitioning, parallel processing, caching, and columnar formats across all four stages, it cut processing time to under two hours.
Technologies That Support Optimization
| Category | Examples | Note |
|---|---|---|
| Distributed frameworks | Apache Spark, Apache Flink | Hadoop MapReduce still exists but has largely given way to Spark |
| Cloud-native platforms | AWS Glue, Google Dataflow, Azure Data Factory | See our best ETL tools for complex data transformation |
| NoSQL for semi-structured data | MongoDB, Cassandra, DynamoDB | Choose by access pattern, not fashion |
| Tool-specific tuning | Informatica pushdown, partitioning, and caching; Alteryx In-DB tools | Covered in our Informatica efficiency guide and Alteryx best practices |
Organizations modernizing legacy pipelines often pair optimization with a wider ETL migration to cloud-native architectures, as in our ETL automation for legacy data migration work and Databricks migration services.
Frequently Asked Questions
Find Your Slowest Stage with DataTerrain
Most slow pipelines are slow in one place, and the fastest fix is finding it. DataTerrain brings 17+ years of ETL and data platform experience and 400+ clients to performance reviews, optimization, and migration, including ETL to Informatica, ETL to SnapLogic, ETL to AWS Glue, and ETL to Informatica IICS.
Related Reading
ETL Data Transformation Solutions | Data Transformation Best Practices in ETL Pipelines | Serverless ETL for Large-Scale Data Transformation | High-Performance ETL Tools for Real-Time Data Processing | Handling Schema Evolution in ETL | ETL Pipeline Automation with Python | ETL Workflow Automation with Apache Airflow | Cloud-Based ETL for Structured and Unstructured Data | Best ETL Tools for Complex Data Transformation | Comparing ETL Frameworks for Cloud Migration | Informatica PowerCenter Workflow Efficiency | Traditional ETL vs Modern ETL | Legacy PL/SQL to Modern ETL | Databricks Migration Services | ETL Automation for Legacy Data Migration | Automating ETL Testing with Python | ETL Solutions